Skip to content Skip to sidebar Skip to footer

AI News

Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens, Grounds Objects, and Calls Tools On-Device

Yesterday, Liquid AI released LFM2.5-VL-3B. It is a 3.1B-parameter vision-language model built for on-device deployment. The model reads digital screens across mobile, web, and desktop. It grounds objects to coordinates, parses documents and charts, and calls tools from text or image input. Liquid AI reports an average of 69.4 across 28 vision benchmarks. That matches…
Read More

Adaptive Experimentation with Meta’s Ax: A Practical Coding Guide

In this tutorial, we explore adaptive experimentation using Meta’s Ax with the modern Client API. We work through a complete workflow where we tune a RandomForest model on a synthetic classification dataset while balancing predictive accuracy against model footprint. We begin by defining a mixed search space with integer, float, log-scaled, and categorical parameters, then…

Read More

Onton Releases Ontology 1: A Neurosymbolic Search Model That is 2.7x More Accurate than the World’s Best E-commerce Search Engines

Onton, a San Francisco-based search and discovery company, has released Ontology 1, a neurosymbolic model for complex, conversational, multimodal product search. On a 90-query benchmark scored by three independent LLM judges, Ontology 1 reached a mean precision@10 of 0.630, against 0.543 for Google Shopping and 0.469 for Amazon. It did this while indexing roughly 1%…

Read More

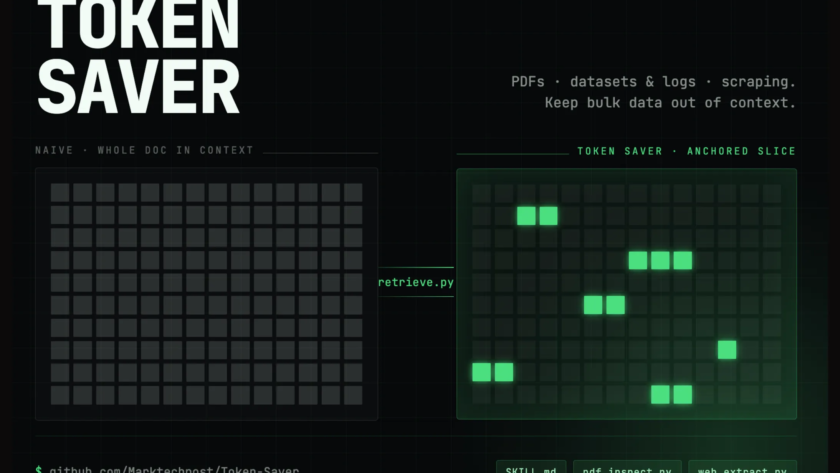
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99%

AI developers, researchers, and professionals frequently hit a frustrating wall when analyzing large documents with LLMs: the hidden, compounding cost of context windows. Pasting a 200-page PDF into a chat isn’t a one-time charge. Because the conversation history is re-sent to the model on every single turn, that massive document is paid for again with…

Read More

NVIDIA Released DeepStream 9.1: Bringing Agentic AI to Vision AI With 13 Skills and Multi-View 3D Tracking

NVIDIA just released DeepStream 9.1. The update targets a persistent problem in video analytics. Tracking one object across many cameras traditionally requires manual camera calibration and complicated calculations. DeepStream 9.1 addresses this with two additions: Multi-View 3D Tracking (MV3DT) and AutoMagicCalib (AMC). Both ship as agentic skills for coding agents. As a result, developers move…

Read More

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas

Datalab has released lift, a 9B open-weights vision model for structured extraction. You pass it a JSON schema, and it returns a JSON object that matches. The model reads PDFs and images directly, then decodes against your schema. This is Datalab’s first model built purely for extraction. The team already ships open-source OCR tools: chandra,…

Read More

Zyphra Release Zamba2-VL: Hybrid Mamba2–Transformer Vision-Language Models That Cut Time-to-First-Token by About an Order of Magnitude

Zyphra has released Zamba2-VL, a family of open vision-language models. The release covers three sizes: 1.2B, 2.7B, and 7B parameters. Each model is built on the Zamba2 hybrid SSM–Transformer backbone. Vision-language models (VLMs) read images and text together. They answer questions about charts, documents, and photos. Most open VLMs use a dense Transformer as…

Read More

A Hands-On Coding Tutorial on Qualcomm AI Hub Models for Classification, Object Detection, and Hardware-Aware Deployment

In this tutorial, we work through an end-to-end workflow for Qualcomm AI Hub Models. We start by setting up the required package, discovering the available model collection, and loading MobileNet-V2 for local PyTorch inference. We also handle an important input-shape issue by converting NHWC image tensors into the NCHW format expected by the model. From…

Read More